TSDFGS
Training Set Determination for Genomic Selection
Finds a training set for genomic selection and the size it needs.
The r-score of Ou and Liao (2019)
TSDFGS


Version 3.0.0 keeps every function of v2 and adds 15 criteria. See what changed.
TSDFGS helps you decide which individuals to phenotype, and how many, before you build a genomic prediction model. Give it genotypes (principal components or markers) and it searches for the training set that optimizes a criterion.
Find what you need
| I want to... | Go to |
|---|---|
| Install and run a first example | Installation, Quick start |
| Pick the training set | optTrain(): reference, guide |
| Decide how many individuals to phenotype | SSDFGS(): reference |
| Read about the criteria | Criteria overview and the table below |
| Check a criterion's definition, source, or license | its page in the table below; license review |
| Score a training set I already have | the *_score() functions, listed under Reference |
| Move code from v2 | Moving from v2 to v3 |
Criteria
optTrain(method = ) takes the name in the last column; criteria() returns this table in R. Each criterion has a page with its definition, the original paper, the authors' repository, and a license review. "Test set" says whether the criterion uses the individuals to be predicted.
| Criterion | Type | Test set | method |
|---|---|---|---|
| r-score | Model-based | yes | "rScore" |
| PEVmean (ridge, PCs) | Model-based | yes | "PEV" |
| CD (ridge, PCs) | Model-based | yes | "CD" |
| A-optimality | Optimal design | no | "AOpt" |
| D-optimality | Optimal design | no | "DOpt" |
| E-optimality | Optimal design | no | "EOpt" |
| CDmax (ridge, PCs) | Model-based | yes | "CDmax" |
| PEVmax | Model-based | yes | "PEVmax" |
| G-optimality (GOPTPEV) | Optimal design | yes | "GOpt" |
| MSPE of ridge regression | Model-based | yes | "MSPE" |
| GVoverall | Genomic variation | no | "GVoverall" |
| GVaverage | Genomic variation | no | "GVaverage" |
| Avg_GRM | Relationship | yes | "AvgGRM" |
| Avg_GRM_self | Relationship | no | "AvgGRMself" |
| Avg_GRM_MinMax | Relationship | yes | "AvgGRMminmax" |
| CDmean | Model-based | yes | "CDmean" |
| CDmean(v2) | Model-based | yes | "CDmeanV2" |
| Partitioning around medoids (PAM) | Clustering | yes | "PAM" |
The r-score is the criterion of Ou & Liao (2019). The others come from the papers named on their pages. TSDFGS is released under GPL (>= 3) and implements every criterion from its published definition in C++ (RcppEigen).
What is tested. Only three criteria are tested carefully: the r-score, PEVmean, and CD, the criteria of v2.4.2. For all 12 routes of optTrain() (with or without sub-populations, with or without a test set), the training sets, scores, and score histories equal the output recorded from v2.4.2.
The other 15 criteria are provided as they are described in their papers, and the code runs without errors on all routes, but we have not checked them carefully. We compared several of them with other implementations (see the license review), and each has a small test against a direct formula. This is not a validation. Please evaluate them yourself on your own data before you rely on them, for example by scoring training sets you know with the matching *_score() function.
Installation
This repository is the home of the package. Every push to main is checked on Linux, macOS, and Windows (GitHub Actions), and the website and the Docker image are built from it.
# Current version of the main branch (needs a C++17 compiler)
# install.packages("remotes")
remotes::install_github("oumarkme/TSDFGS")

# A given release, for example v3.0.0
remotes::install_github("oumarkme/TSDFGS@v3.0.0")

# Source package of a release (the file also attached to each GitHub release)
install.packages("https://github.com/oumarkme/TSDFGS/releases/download/v3.0.0/TSDFGS_3.0.0.tar.gz", repos = NULL)

# From CRAN, once the version is accepted there
install.packages("TSDFGS")
Without installing anything, use the Docker image (R, compilers, and TSDFGS included):
docker run --rm -it -v "$PWD":/work ghcr.io/oumarkme/tsdfgs:latest R
| Needed | Version |
|---|---|
| R | 4.0 or later (tested with 4.4.3 and with R-devel, release, and oldrel in CI) |
| C++ compiler | C++17 (GCC, Clang, or Rtools on Windows) |
| Rcpp, RcppEigen | Installed from CRAN with the package (tested with 1.1.2 and 0.3.4.0.2) |
| ggplot2 | Optional; only for the figures of SSDFGS() |
| OpenMP | Optional; for multi.threads and threads. Without it (default macOS compiler) the package runs on one thread and returns the same values |
The article Installation and environments has the details for each system. Old versions are on the releases page.
Version used in the manuscript
The manuscript (Ou & Liao, 2019) used TSDFGS 1.0, the first CRAN release (2019-03-07). The r-score and the search of this package are the method of that paper. To run version 1.0 itself, install it from the CRAN archive:
install.packages("https://cran.r-project.org/src/contrib/Archive/TSDFGS/TSDFGS_1.0.tar.gz", repos = NULL, type = "source")
Quick start
library(TSDFGS)
data(geno)                                   # 404 rice accessions, principal components
g <- as.matrix(geno)[, 1:15]

# 30 of the first 100 accessions to phenotype, to predict accessions 101-150
fit <- optTrain(g, cand = 1:100, n.train = 30, test = 101:150, seed = 1)
fit$OPTtrain                                 # rows to phenotype
r_score(g[fit$OPTtrain, ], g[101:150, ])     # criterion of the chosen set

# How many individuals are enough? (slow; use multi.threads = TRUE on Linux or macOS)
res <- SSDFGS(geno)
res$OC.fig
More in the Getting started guide.
Main functions
| Function | Purpose |
|---|---|
optTrain() |
Find the optimal training set (more) |
SSDFGS() |
Find a reasonable training set size (more) |
r_score(), pev_score(), cd_score(), ... |
Score of a given training set, one function per criterion |
criteria() |
List the criteria |
FGCM(), nt2r() |
Building blocks of SSDFGS() |
The packages STPGA (GPL-3) and TSODBG (GPL >= 3) implement several of the same criteria in R; we used them to check our results (see the license review).
What changed from v2 to v3
New in v3.0.0: 15 added criteria (see above), the criteria() function, and the lambda argument of optTrain().
Nothing you call has changed. All exported functions keep their names and arguments, and the method is the one published in 2019.
| v2.4.2 | v3.0.0 | |
|---|---|---|
| Structure | Search loop in R (12 copies of the same code), scores in C++ | R is the interface; scores and the search run in C++ (Rcpp and RcppEigen) |
| Speed | Reference | 2 to 174 times faster per iteration in our benchmark (see below) |
| Scores | Single precision (float) |
Double precision; equal to v2 to about 1e-7 |
| Reproducing v2 | n/a | options(TSDFGS.legacy_float = TRUE) with the same seed returns the v2.4.2 training set for all 12 routes (tested) |
| Random search | set.seed() only |
Also optTrain(seed = ) |
Result of optTrain() |
OPTtrain, TOPscore, ITERscore |
Same, plus n.iter and converged |
Small min.iter |
Error "the condition has length > 1" below 5 * sqrt(length(cand) * n.train) |
Works |
| Sub-populations without a test set | cand had to be 1:nrow(geno) |
Any cand |
| Input checks | Cryptic errors | Clear errors for missing values, too large n.train, wrong row numbers |
| Dependencies | dplyr, ggplot2, latex2exp, parallel, Rcpp, RcppEigen | Rcpp and stats (ggplot2 optional) |
| Figures | ggplot2, red and blue | ggplot2 if installed, colorblind-safe Okabe-Ito colors |
| Quality | No tests | Tests, including regression tests against recorded v2.4.2 output |
| Build and test | n/a | Apptainer recipe in env/ |
| Website | One page per function | New site with a guide and articles |
Speed on the rice principal components (one core, same seed and iteration count; median of one run per case):
Milliseconds per iteration of optTrain() (rice principal components, n.train = 50 to 100):
| PCs (p) | Case | v2.4.2 | v3.0.0 | Speed-up |
|---|---|---|---|---|
| 10 | CD, targeted, n=50, test=300 | 0.092 | 0.015 | 6.3x |
| 10 | PEV, untargeted, n=100 | 0.074 | 0.006 | 11.7x |
| 10 | r-score, untargeted, n=100 | 1.252 | 0.007 | 173.7x |
| 50 | CD, targeted, n=50, test=300 | 0.410 | 0.234 | 1.8x |
| 50 | PEV, untargeted, n=100 | 0.347 | 0.085 | 4.1x |
| 50 | r-score, untargeted, n=100 | 2.786 | 0.136 | 20.4x |
| 404 | CD, targeted, n=50, test=300 | 26.624 | 0.250 | 106.5x |
| 404 | PEV, untargeted, n=100 | 27.816 | 0.831 | 33.5x |
| 404 | r-score, untargeted, n=100 | 17.701 | 1.319 | 13.4x |
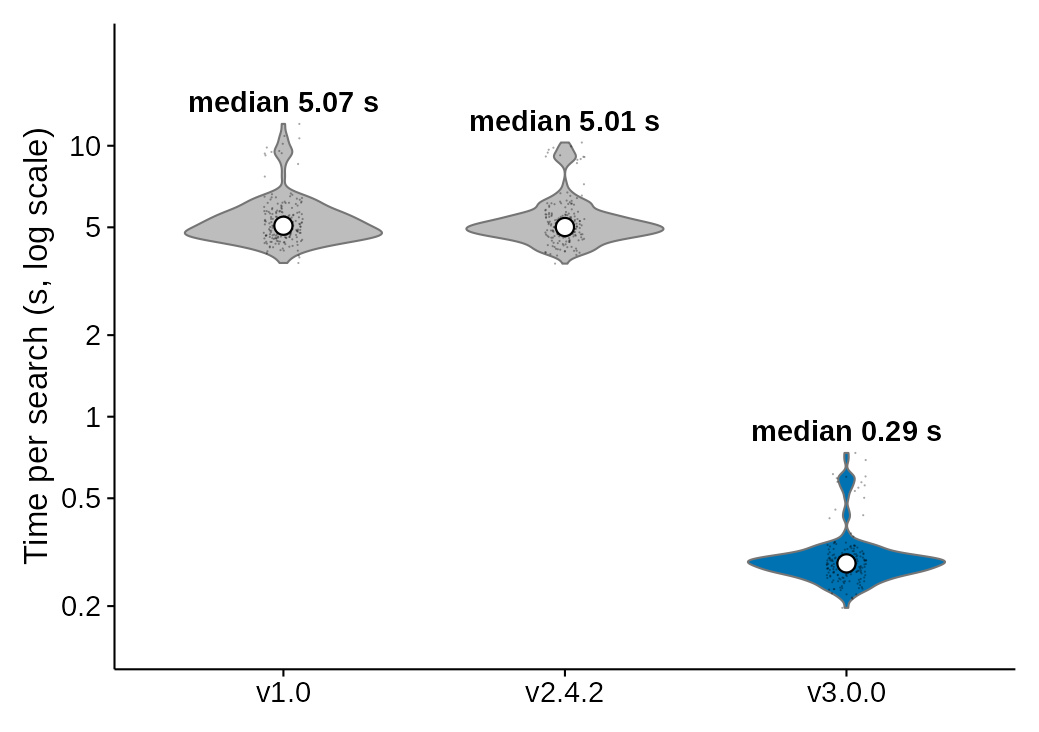
Speed with 50 cores. We ran 200 independent r-score searches (untargeted, 100 of 404 rice accessions, 50 principal components) on 50 cores, with TSDFGS 1.0, 2.4.2, and 3.0.0. Versions 1.0 and 2.4.2 have no multithreading, so they ran as 50 forked processes (parallel::mclapply). Each violin shows the time of the 200 searches; the white dot is the median. The median search took 5.07 s with version 1.0, 5.01 s with 2.4.2, and 0.29 s with 3.0.0 (17.6 times faster than 1.0). The whole job took 29.1 s, 29.5 s, and 1.9 s with the same forking, and 1.5 s with the OpenMP threads of 3.0.0 (19.6 times faster than 1.0). The spread within a violin comes from the stopping rule, which ends each search after a different number of iterations.
Parallel simulation. SSDFGS(), FGCM(), and nt2r() run their independent searches with OpenMP when you set multi.threads = TRUE or threads = n. On a Linux server limited to 50 threads (100 searches, 404 rice accessions, 50 PCs, wall time):
| Method | Threads | Seconds | Speed-up |
|---|---|---|---|
| Serial | 1 | 300 | 1.0x |
mclapply (v2 way) |
10 | 32 | 9.3x |
mclapply (v2 way) |
50 | 11 | 27x |
| OpenMP | 10 | 31.5 | 9.5x |
| OpenMP | 25 | 14.8 | 20x |
| OpenMP | 50 | 10.1 | 30x |
OpenMP is about as fast as mclapply. What it adds: the same values for any number of threads (tested), no forked copies of the data, and Windows support. At 50 threads 100 searches are too few to keep every thread busy. optTrain(threads = ) lets one search use several threads: the matrix products inside one search (only with several hundred columns) and, for the targeted r-score and PEV search, the 30 candidate sets of each generation.
The full list is in NEWS.md, the article Moving from v2 to v3 has the details.
Kept on purpose. The r-score code multiplies the test set by 1 - 1/n0 where a centering matrix may be intended. It stays as published, so that results do not change.
Example dataset
Zhao et al. (2011) published the rice genome data used as an example. The raw dataset is on the Rice Diversity website. The pre-arranged data are in this repository and load with data(geno) and data(subpop), or:
download.file("https://github.com/oumarkme/TSDFGS/raw/main/data/geno.rda", "geno.rda")
load("geno.rda")
Reproducible environment
We tested v3 with R 4.4.3, Rcpp 1.1.2, RcppEigen 0.3.4.0.2, and GCC 16.2.0. All versions are pinned in environment.yml, and the Docker image contains them. Use either of two ways to get the same software:
# Docker image with R and TSDFGS installed (built and tested by GitHub Actions)
docker run --rm -it -v "$PWD":/work ghcr.io/oumarkme/tsdfgs:3.0.0 R

# conda / mamba environment with the pinned versions; then install TSDFGS from a clone
git clone https://github.com/oumarkme/TSDFGS.git && cd TSDFGS
mamba env create -f environment.yml
mamba activate TSDFGS
R CMD INSTALL .
Use a release tag such as 3.0.0 in your analyses, because latest follows the main branch. The article Installation and environments also covers a small conda environment, Apptainer, and building the image yourself.
Development
Build and test with the same software versions in an Apptainer image:
env/build_sif.sh <work_dir>         # writes env/TSDFGS.sif (git-ignored)
apptainer exec --bind $PWD:/work --pwd /work env/TSDFGS.sif Rscript -e 'devtools::test()'
Authors
- Jen-Hsiang Ou, Ph.D.
- Author, maintainer
- E-mail: oumark.me@outlook.com
- Department of Medical Genetics, National Taiwan University Hospital, Taipei, Taiwan
- Po-Ya Wu, Ph.D.
- Author
- E-mail: Po-Ya.Wu@hhu.de
- Institute for Quantitative Genetics and Genomics of Plants, Heinrich Heine University, Düsseldorf, Germany
- Chen-Tuo Liao, Ph.D.
- Author, thesis advisor
- E-mail: ctliao@ntu.edu.tw
- Department of Agronomy, National Taiwan University, Taipei, Taiwan
Citation
Ou, J.-H., & Liao, C.-T. (2019). Training set determination for genomic selection. Theoretical and Applied Genetics, 132, 2781-2792. https://doi.org/10.1007/s00122-019-03387-0